How I built this site with an agent workforce
AI-narrated
A synthetic voice reading the text on this page.
I relaunched this site as a positioning page for an engineering leader. Coding agents built almost all of it. Astro was new to me going in and turned out to be a good call. It ships static pages, reads posts straight from markdown, and builds fast enough to keep the loop tight.
I have managed engineers for years. Directing agents felt like that work, not like coding. It is closest to ramping a new direct report. You choose what to delegate, how often to review, and which corrections become standing rules. The bar flows one way, from you to the agent. Bend your judgment to fit how the agent executes and you have it backwards.
The design language came first. I tried looks on ggprompts.com until one felt like mine, an op-art direction, and handed the agent that reference to build toward. Skip this step and you inherit the median of the training data, work that is competent and forgettable.
Then I made the priorities executable. Accessibility wins every conflict, and a Playwright suite enforces the rule by running axe, a keyboard walkthrough, forced colors, reduced motion, 320px reflow, and screen-reader narration inside a git pre-commit hook. Every view gets demoed locally before it publishes. CI deploys on merge.
The screen-reader launch gate is where I got the workflow wrong. It runs real VoiceOver on a macOS CI runner, driven through guidepup. Getting it green took a string of small fixes, and I debugged each one the expensive way. Push, open a PR, wait for the runner, read the failure, patch, push again. Each near miss cost a full runner cycle to disprove.
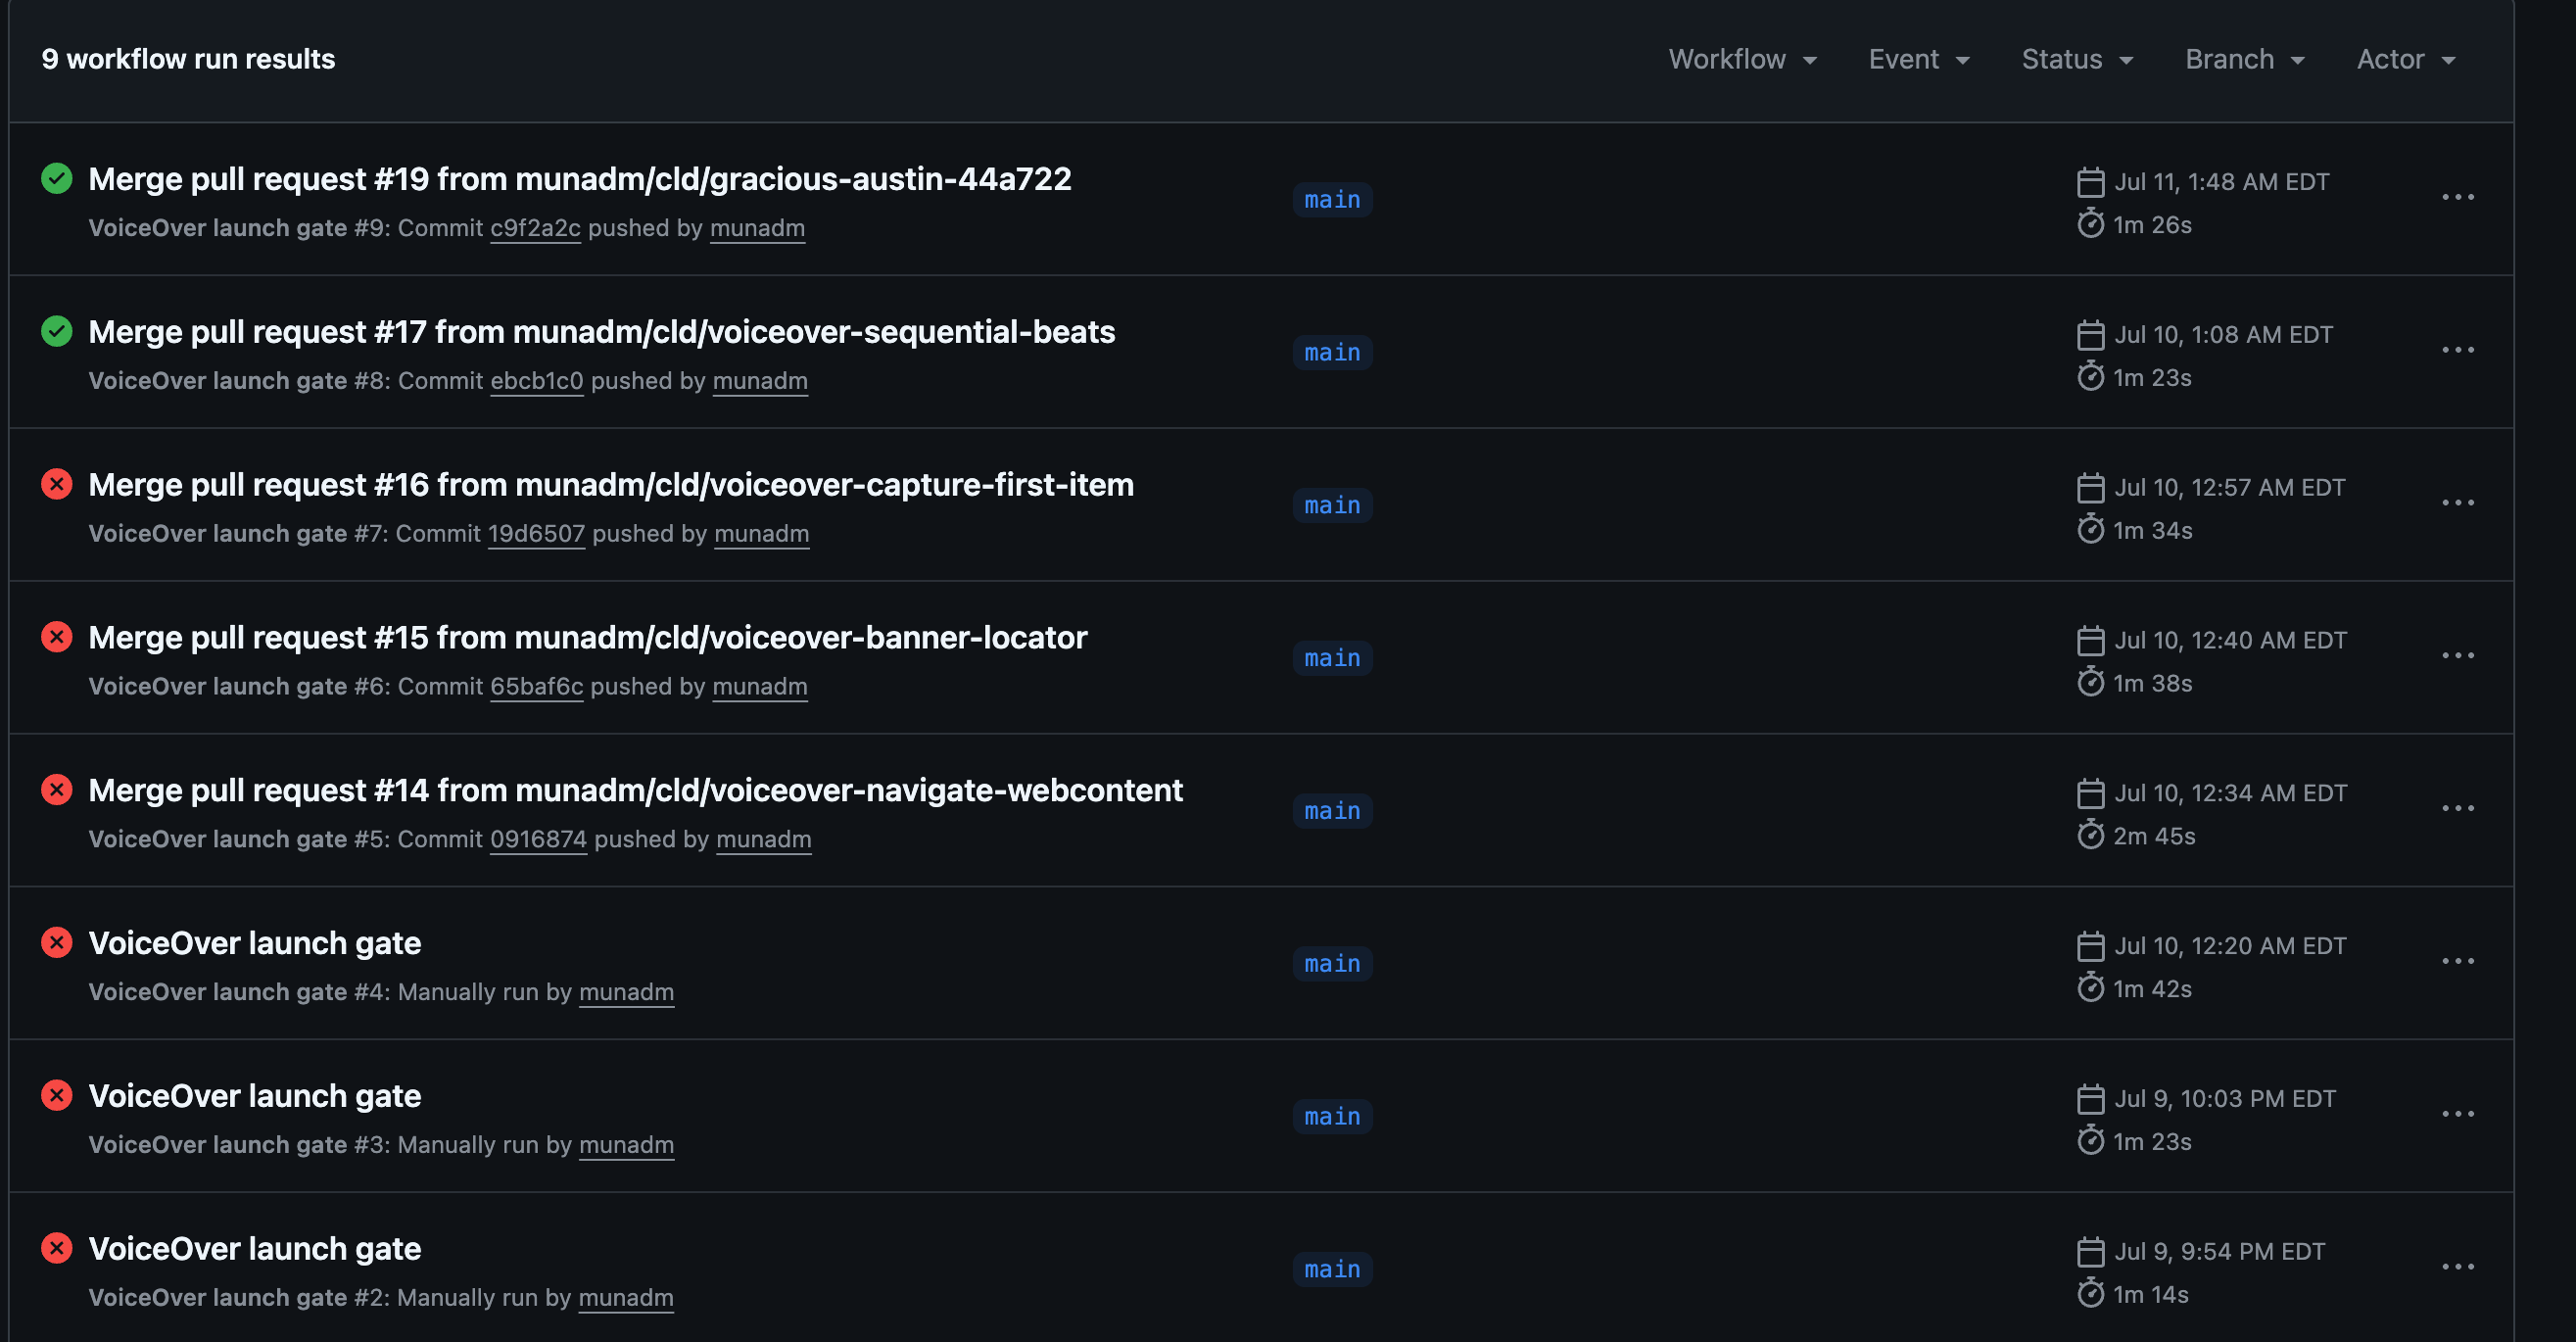
I stopped and questioned the loop instead of the next patch. We restructured it so the same narration check runs locally through a virtual screen reader in the pre-commit hook. Regressions fail on my machine in seconds and CI confirms once. Every failure in that stretch had been a harness bug, not an accessibility defect. I had paid runner time to debug my own test rig.
Planning is not a kickoff phase. My objectives held for the whole build, but the approaches under them kept needing another pass as nuances surfaced. Now, when a loop’s outcomes drift from the session’s goal, I stop and replan that approach before it eats more tokens, more loops, more infrastructure.
I left the economics out on purpose. What this build cost in time and tokens, and where the spend concentrated, deserves its own post. If you run agents through builds of your own, I want to compare notes.